Low-Code Apache Flink for Real-Time
Decision Logic
Build on Apache Flink without the complexity. Turn complex stream processing into visual decision logic you can deploy instantly and adapt continuously, without touching Flink code.
Engineers set up integrations. Business teams own the logic.
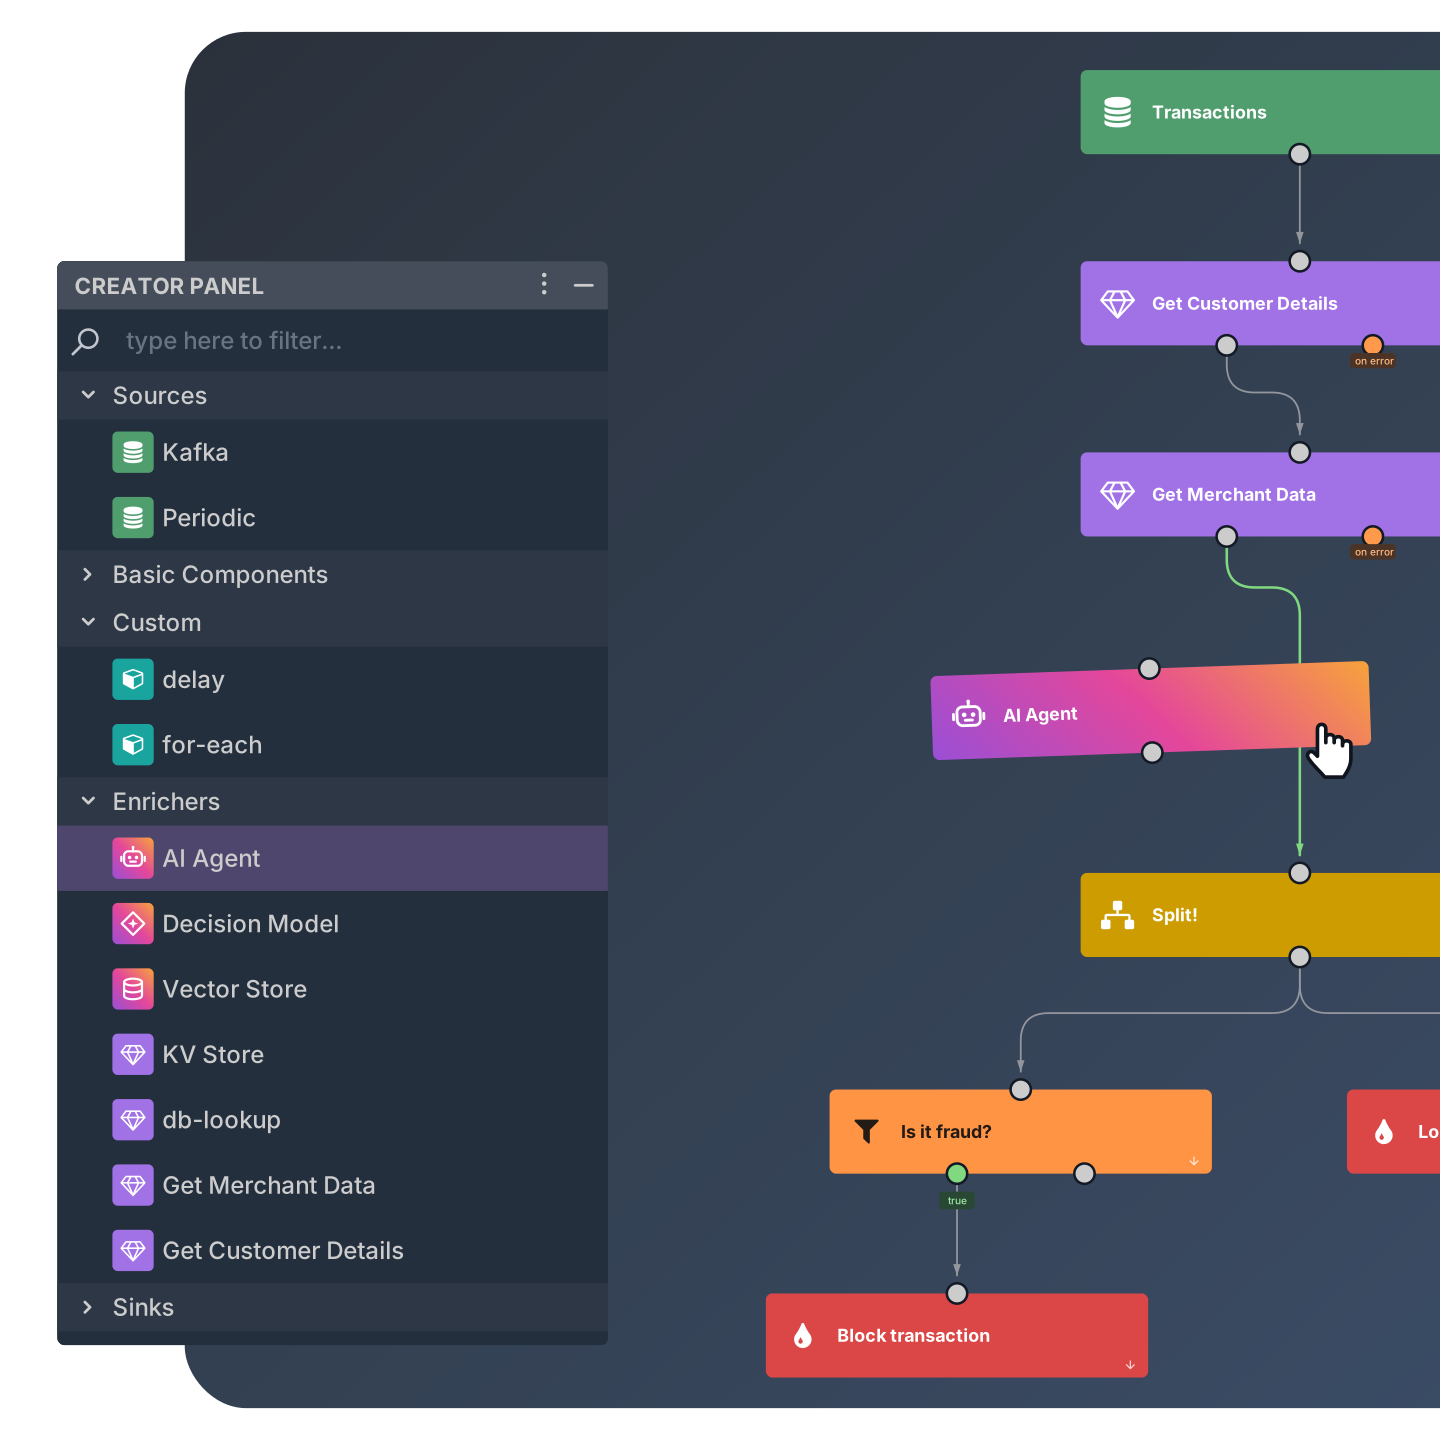
Engineers connect them once.
Business teams drag them into scenarios.
 Apache Kafka
 Confluent
 Redpanda
 Azure Event Hubs
 MLflow
 Databricks Unity Catalog
 PostgreSQL
 Snowflake
 Amazon Redshift
 Aiven
 OpenAPI
Why teams move beyond building directly on Apache Flink
Apache Flink is a powerful engine, but building real-time decision logic directly on it requires too much code, specialist expertise and too much engineering effort.

Business teams depend on developers for every business logic change
Every rule update, threshold adjustment, or new condition requires a developer, a code review, a deployment. A fraud analyst wants to change a threshold from 500 to 800 – that's a Jira ticket, a sprint, three people involved.
With Nussknacker: The analyst changes the value in the visual editor, tests on historical data, and deploys. Time: 15 minutes.

The hidden cost of building decision logic directly on Apache Flink
The average Flink greenfield takes weeks and 40 – 115 engineer-days before the first business logic runs. Write the job in Java. Configure serialization. Build the JAR. Set up CI/CD. Every new use case restarts the cycle.
With Nussknacker: New logic from design to production – in hours, not months.

Engineers spend most of their time on ops, not business logic
Checkpoints, RocksDB tuning, connector reliability, Kubernetes orchestration, observability - Flink infrastructure consumes engineering capacity that should go toward delivering value.
With Nussknacker: Zero manual savepoints, zero 3 AM restarts. Deploy and rollback in seconds.

Flink expertise can become a bottleneck
Self-managed Apache Flink costs $1.5 – 2.5M per year – up to 78% is salaries, not servers. Streaming data engineers are among the hardest roles to fill.
With Nussknacker: One Flink engineer sets up the platform. Business teams build and modify logic independently.
From visual design to production deployment
The complete platform for designing, deploying, and continuously adapting operational decision logic.
Visual drag-and-drop job builder
Build on Flink. Use the visual interface, not code syntax. Wire connectors by dragging nodes on a canvas.
SpEL expressions – spreadsheet-level accessibility
Domain experts write conditions as readable expressions. No Java, no boilerplate, no compile step.
One-click deployment to production Flink
From design to running Flink job: testing, locking, and rollback built in. No CI/CD config required.
Full Flink capabilities, exposed visually
Flink CEP, Flink SQL, stateful aggregations, time windows - all through the visual interface.
Built-in testing, version history, and one-click rollback
Test workflows on real historical data before deploying. Roll back any version in seconds - no CI/CD intervention needed.
Full observability out of the box
Per-node event counts, behavioral metrics, dashboards - no custom instrumentation needed.
Turn live events into business decisions
Build the decision on one canvas, from the incoming event through enrichment, aggregation and conditions to the action. Nussknacker deploys the scenario as a running Apache Flink job.
Real-time business needs real-time decision logic
Explore how business and data teams respond faster to changing business conditions with Nussknacker.
Real-time fraud detection at scale
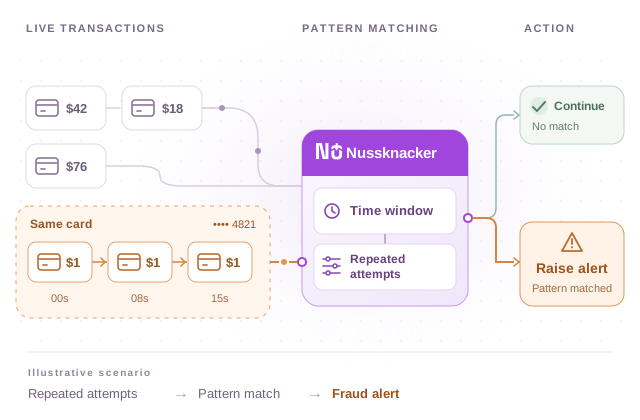
Define complex event patterns in a visual editor: card testing sequences, velocity rules across channels, and geographic anomalies – without writing Flink code. Business risk teams own and update detection logic directly, without routing every change through engineering.
Deploy rule changes in minutes, not weeks. Run pattern matching across millions of transactions per second with full Flink CEP under the hood – and capture multi-step sequences that span time windows without touching a line of code.
Stream ML predictions at scale
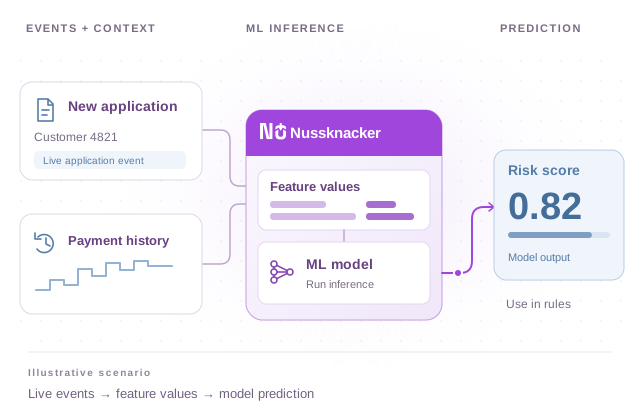
Plug any ML model into your streaming pipeline as a native enrichment step. Nussknacker handles batching, latency management, and model versioning – your data scientists iterate on model logic independently while the pipeline runs at full throughput.
Feature engineering and model calls become drag-and-drop nodes. No Flink expertise is required to operationalize ML at scale, and model version swaps happen without re-deploying the pipeline – inference latency stays consistent.
Business logic at stream speed
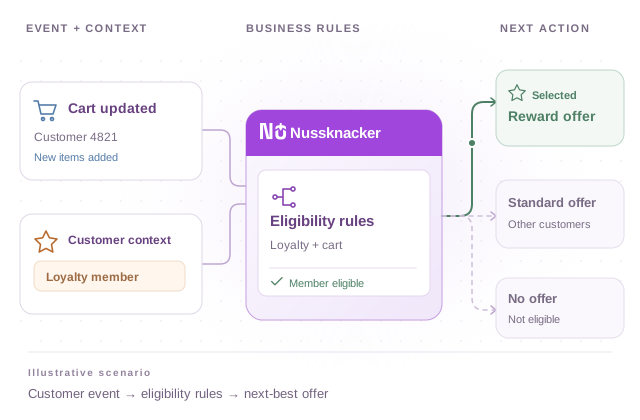
Replace batch decision engines with streaming rules that react in real time. Credit decisions, pricing adjustments, and personalization logic run as stateful Flink computations – owned and updated by business analysts, not engineers.
Audit trails, rollback, and A/B testing of decision variants are built in from day one. When a rule changes, the analyst deploys it directly – no ticket, no sprint, no waiting for the next release cycle.
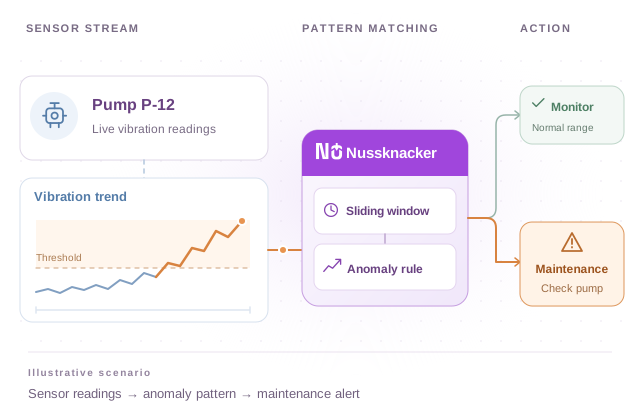
Predict failures before they happen
Ingest high-frequency sensor streams and detect anomaly patterns using Flink CEP without writing Java. Maintenance teams configure alert thresholds and complex temporal patterns through Nussknacker's visual interface – no platform specialist required.
Reduce unplanned downtime and maintenance costs by acting on predictive signals, not reactive alarms. When thresholds need adjusting, the team updates them directly without re-deploying the pipeline or involving engineering.
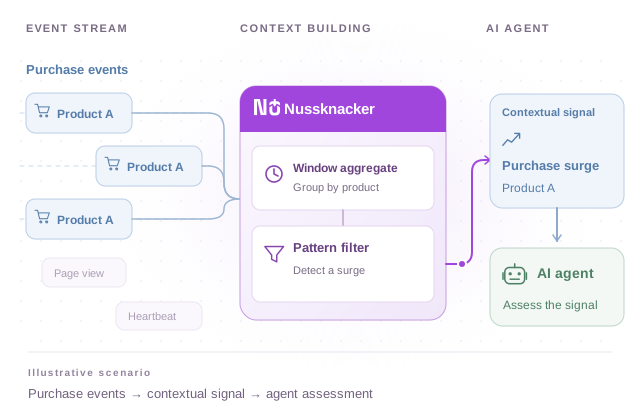
Flink CEP as the nervous system for AI agents
AI agents fail at scale when connected directly to raw event streams. Platforms processing over 500,000 events per second cannot route each one to an LLM – the cost alone makes it impossible. Flink CEP and window aggregations solve this: complex event patterns are detected and signals pre-aggregated across time windows before any AI agent is involved, cutting inference volume by over 99%.
With Nussknacker, business define CEP patterns and sliding window aggregations visually. Agents receive grounded, pre-aggregated signals – not noise. The result is autonomous decisions that are fast, cost-efficient, and auditable.
The missing layer between Flink and your business
If your decision logic changes faster than engineers can ship it and your data moves faster than batch jobs can handle it – that's where Nussknacker belongs
| Flink RAW | Own Delivery System | Nussknacker | |
|---|---|---|---|
| Time to first production value | Months (Flink setup first) | Months (platform first) | Weeks |
| Who deploys a rule change | Engineers only | Business teams* | Business teams |
| Time to ship a logic change | Sprint (1–2 weeks) | Days | Hours |
| User complexity | High | Medium | Low |
| Flink expertise required | High (ongoing) | High (build + maintain) | Setup only |
| Deployment cycle | CI/CD Pipelines | Dedicated deployment engine | One-click, no CI/CD |
* Only after the custom solution is fully built and deployed
Built for enterprise, proven at scale
Trusted in production for over 8 years across telecom, fintech, and enterprise environments
Rule deployment: 2 weeks → 2 hours
“Before Nussknacker, every change to our fraud detection rules required an engineering sprint. Today, our analysts deploy updated rules in hours, without writing a line of code.”
Domain experts adapt logic daily - no code required
“The visual designer changed how our teams collaborate. Engineers set up the integrations once. Business teams own the logic from that point on.”
Built by TouK - 20+ years in JVM and data engineering for enterprise clients
Deploy your first real-time job in 15 minutes
Build your decision logic visually, test it on sample events, and deploy it to process your event stream.