Real-Time Decision Automation
Domain experts build decision logic as flow diagrams and call ML models in them. Nussknacker serves the models and runs each scenario on event streams or as a request-response service.
Built for rapid ML inference
Nussknacker seamlessly integrates machine learning with traditional decision algorithms.
When using ML models in decision scenarios, you get input data transformations, suggestions and validation, testing, one-click deployment and all the other advantages of Nussknacker's low-code interface.
When data scientists build their models, they don't have to worry about serving them. They work in familiar technologies - scikit-learn, PyTorch, TensorFlow (and many more), provide the models and Nussknacker takes care of the rest, using its own ML runtime.
Built with domain experts in mind
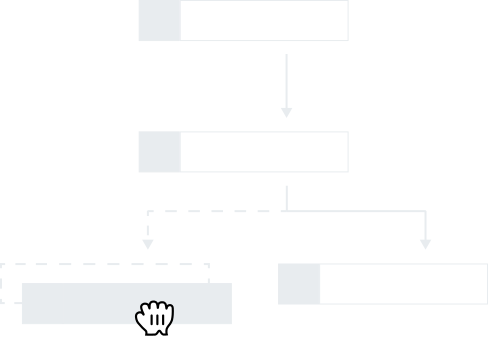
Nussknacker allows domain experts to define decision algorithms in the most natural way. Instead of sets of interdependent rules or SQL statements, they work with easy-to-follow and understand flow diagrams.
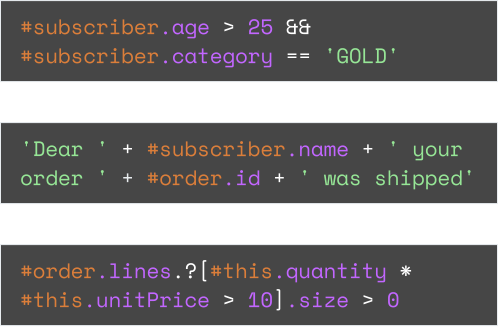
For logical conditions, calculations and other expressions that complement the diagrams there's a powerful expression language. It's based on SpEL (Spring Expression Language) and supports advanced querying and manipulation of data.
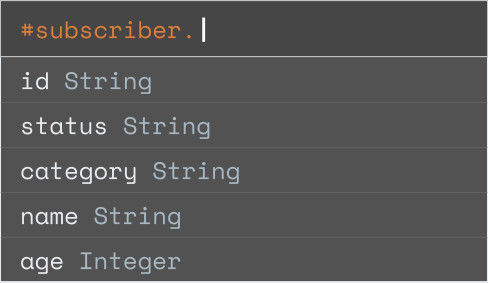
To make writing those expressions easier, Nussknacker integrates with various metadata sources, to automatically discover the structure of input and output data. This information is utilized by advanced contextual expression suggestions, autocompletion and validation mechanism.
Enrich the data, enhance the decisions
The data in the event that triggers a decision is often not enough to make the decision. Nussknacker can enrich it with information from various sources: private and public APIs, databases and machine learning models.
That doesn't mean domain experts have to worry about addresses, credentials etc. They can focus on business logic because Nussknacker hides all of the technical details under the hood. And, no matter the enrichment source, Nussknacker, as always, helps users by using available metadata to provide automatic suggestions and validation.
Test first, monitor the results
Nussknacker wants users to feel safe and confident about the changes they make. That's why it provides different testing and debugging mechanisms.
You can test on data recorded from a live environment or provide your own test cases. You can also monitor execution paths of a running scenario for debugging purposes.
And if you need more technical details, Nussknacker makes numerous metrics available on a Grafana® dashboard out of the box. You can easily check scenario throughput, statistics about decisions made, errors and more.
Deploy anytime, all the time
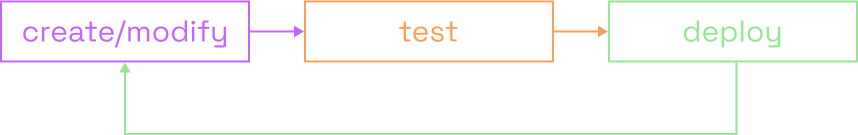
Nussknacker encourages iterative improvements of decision algorithms. Once created or modified, decision scenarios are deployed for execution with a click of a button. And you can always revert to an older version or compare different versions of a scenario, thanks to full version history.
Built with flexibility in mind
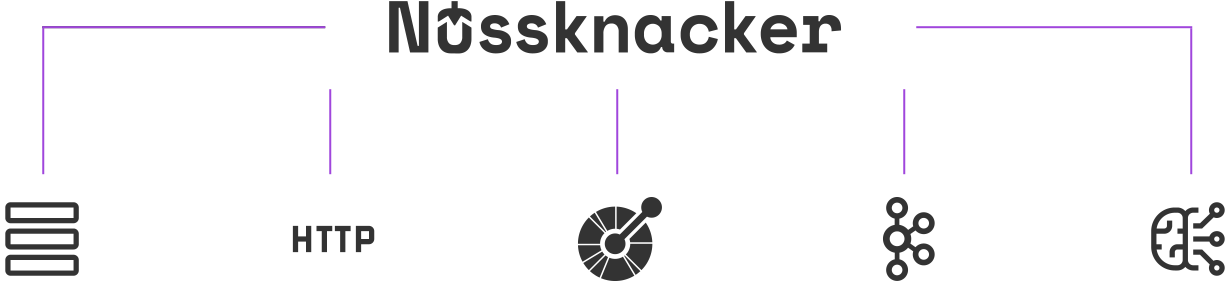
From an architectural point of view, Nussknacker is a decision service. So we had to make it fit various event driven architectures, streaming and request-response.
In streaming use cases Nussknacker can connect directly to any Kafka-compatible streaming platform. Or, if you don't want to use Kafka, Nussknacker also has an HTTP interface with a subscription mechanism that can receive input streams and send output streams over HTTP.
For synchronous, request-response use cases Nussknacker creates an OpenAPI service for every decision scenario.
And whatever the source of input data, Nussknacker can enrich it with information from:
- any REST endpoint with an OpenAPI definition
- any database available via JDBC
- by inferring ML models prepared in one of the popular technologies such as Scikit-learn, PyTorch, TensorFlow, ONNX, PMML or as a custom Python function
As straightforward or as sophisticated as you need
There are two engines available in Nussknacker, that focus on different needs:
Lightweight Kubernetes-native engine if you want to deploy Nussknacker simply as just another service on your platform
Flink engine if your business logic requires data aggregation or other ways of stateful stream processing
No matter which engine you choose, you always get enterprise grade performance: horizontal scalability, high availability, high throughput and low latency.
From a free trial to millions of events per second
Build your first scenarios free for 3 months on SaaS. Higher plans connect more of your systems, add support and run on your own infrastructure. Custom is priced on the throughput you need.
Start free trial Compare all plans
The Nussknacker core is open source under the Apache 2.0 license on GitHub. Paid plans add support with set response times and enterprise integrations.
-
Try it on your use case
3 months free on SaaS
Connect up to 5 kinds of integrations and build your first scenarios. You need only an email address to start.
-
Run in production
from $480 per month, Custom priced on throughput
Starter and Professional connect more of your systems and come with standard support. Enterprise and Custom add every integration, run on SaaS, BYOC or on-prem, and scale to millions of events per second.
From the Nu Blog
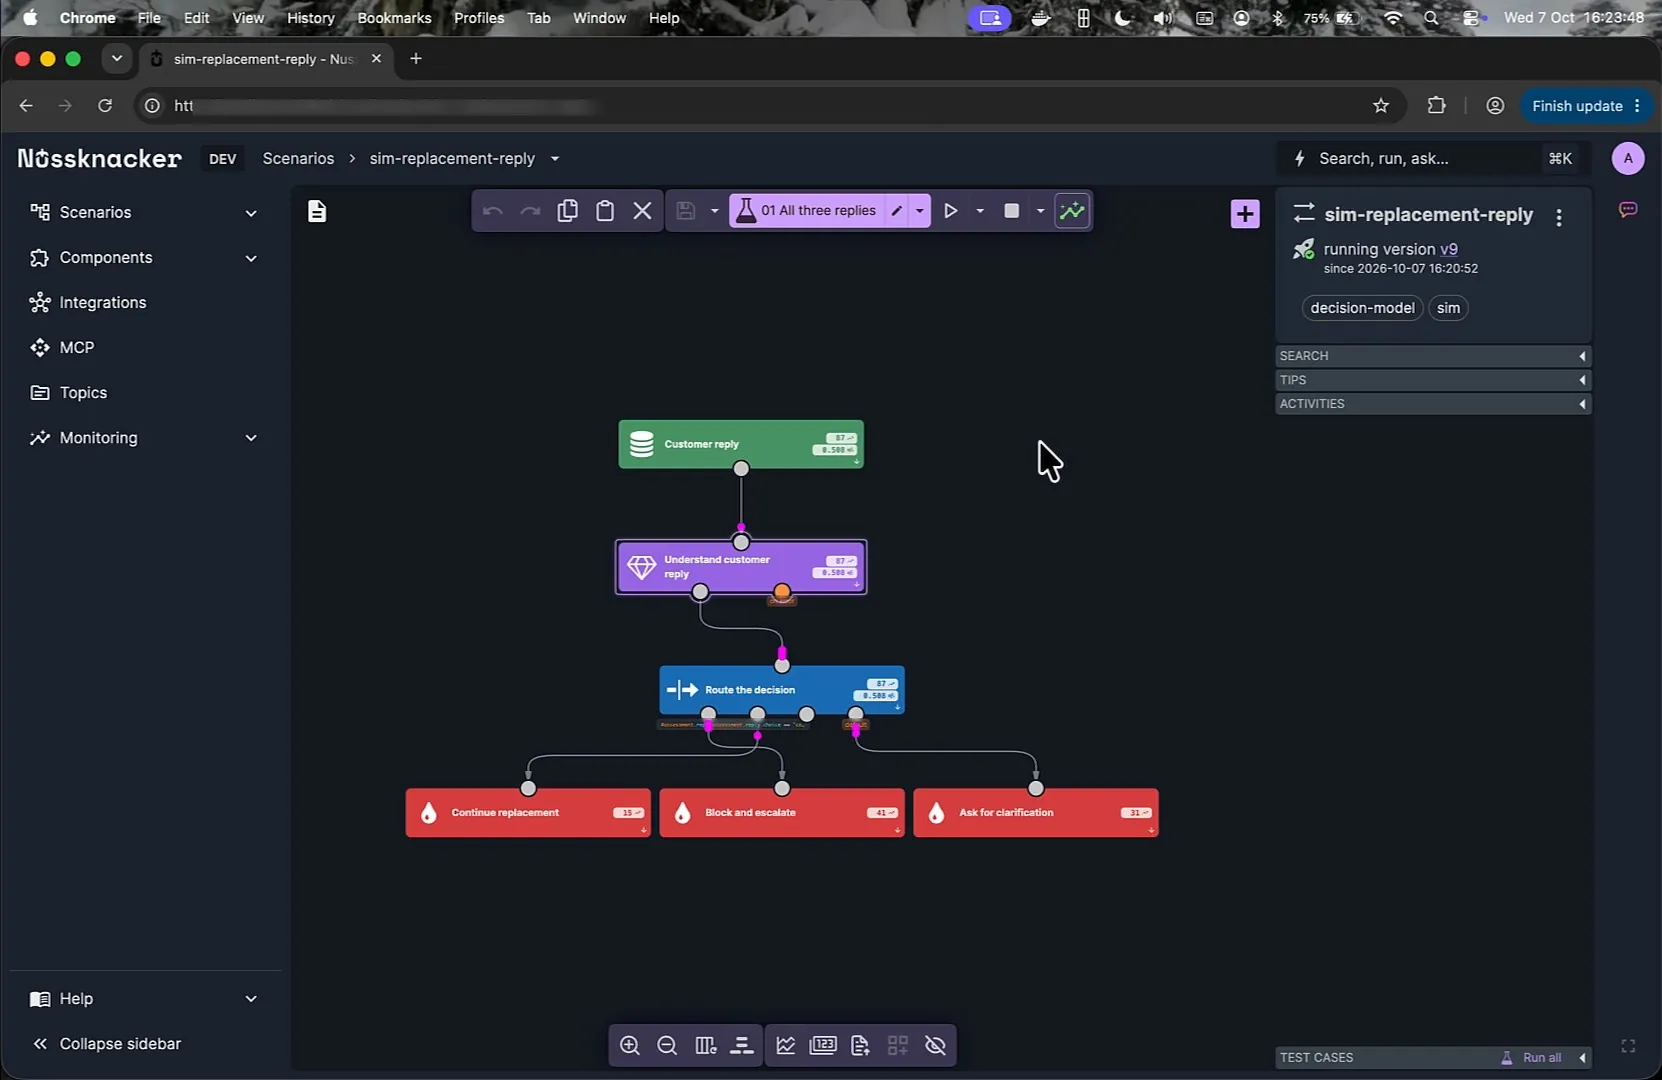
Decision models in Nussknacker: typed AI decisions for Kafka and API workflows
Decision models like TypeSafe Jev and Cloudflare Clef return typed answers with probabilities. See how to add one to a Nussknacker scenario and what you gain.
What is new in Nu – September 2026
Nussknacker in September 2026: Change Data Capture for tables, nodes with named outputs, a WebSocket Server source and live data for Request-Response.
What is new in Nu – August 2026
Nussknacker in August 2026: deployment targets, the World Map component, improved enum support, improved Compare versions and more.
Ready to see it on your data?
Book a call with our team to walk through your use case, or send us a question.